



MLOps (machine learning operations) is the discipline of getting machine learning models into production and keeping them accurate, safe and affordable once they are there. It covers versioning, automated testing and deployment, monitoring for drift, retraining and governance. For LLM and agent products it extends to evals, tracing, prompt versioning and guardrails. Without it, models degrade quietly and every update is a manual gamble.
Adoption is no longer the hard part; running AI reliably is. Stanford’s AI Index puts organisational AI adoption at 88%, while documented AI incidents rose to 362, up from 233 the year before.
When you need MLOps, and when you don’t yet
A model in a notebook is a prototype. Google Cloud’s MLOps guidance points out that only a small fraction of a real-world ML system is the ML code. The rest is data, validation, serving and monitoring.
Google describes three maturity levels:
- Level 0, manual: notebooks, hand-offs to engineers, rare releases, little monitoring.
- Level 1, pipeline automation: the training pipeline is deployed, validation runs automatically and the model can retrain on fresh data.
- Level 2, CI/CD automation: pipeline components themselves are built, tested and deployed automatically.
Most smaller companies should aim for level 1 on the models that matter. You need MLOps when a wrong prediction costs money, when the model needs updating more than a couple of times a year, or when more than one person changes it.
You probably don’t need it yet if the model hasn’t proved its value in a pilot, or if a rules engine would do the job. Building a platform before you have a model worth running burns budget without shipping anything.
Building the core pipeline: versioning, registry, CI/CD and retraining
ML behaviour depends on data as much as code, so version three things together: the code, a pointer to the training data, and the trained model with its configuration. If you can’t say which data produced today’s live model, you can’t debug it, roll it back or explain it to an auditor.
Model registry
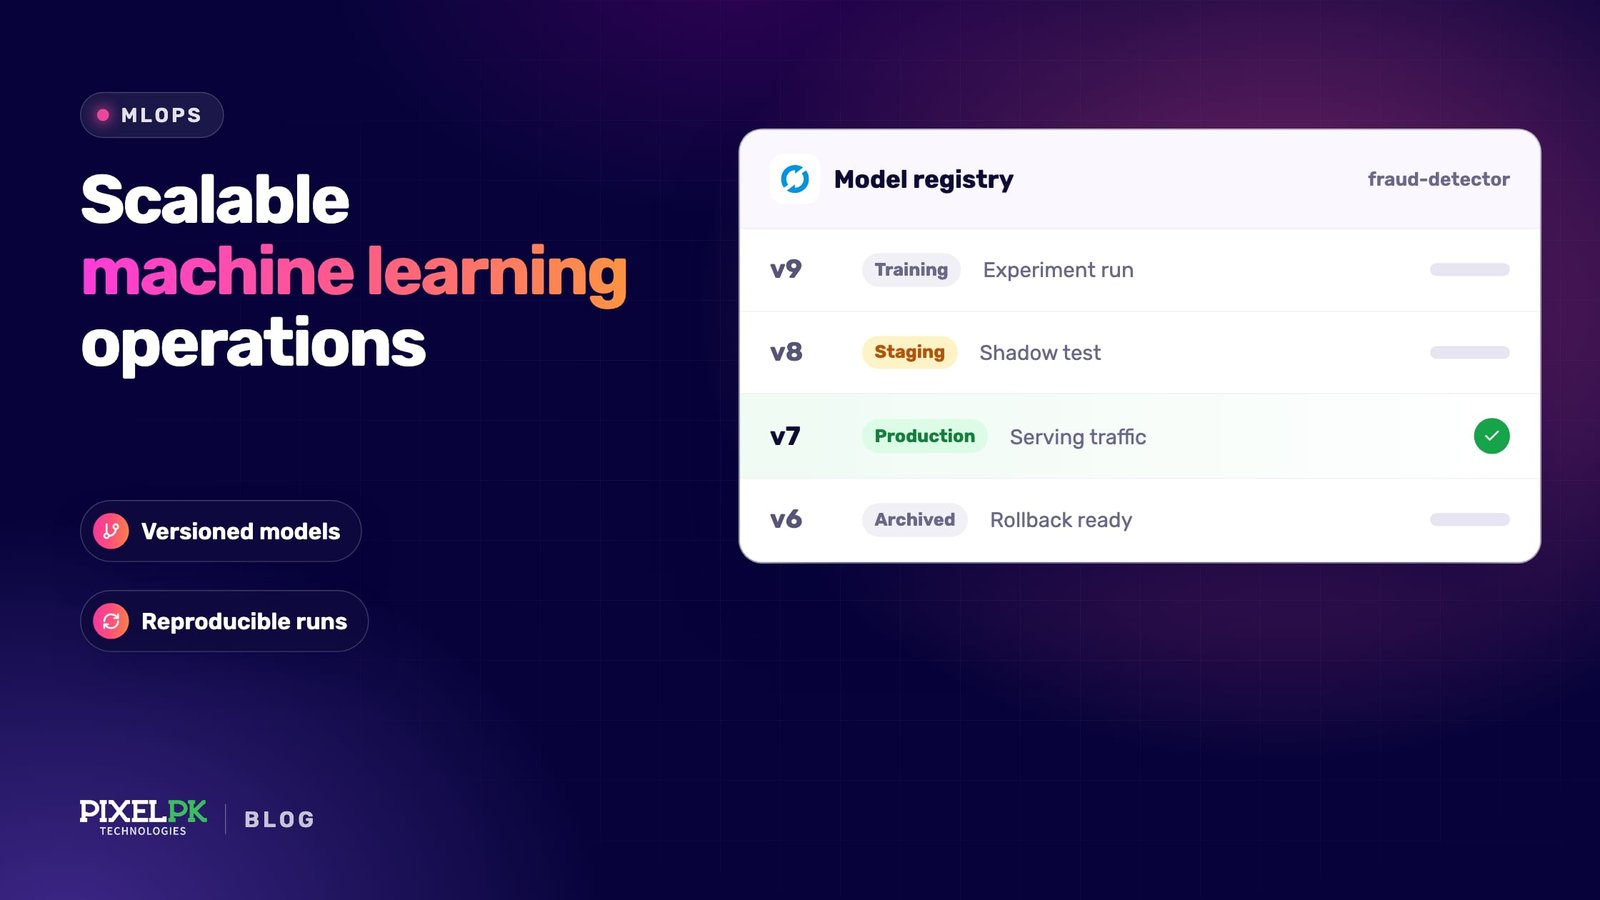
A model registry is the single catalogue of trained models, their versions, metrics, lineage and approval status. It tells you which model is live, who approved it and what it beat. Versions carry aliases such as “candidate” and “champion”, so deployment is a pointer change and rollback takes minutes rather than a retraining run.
CI/CD for models
Continuous integration for ML validates incoming data against an expected schema, retrains reproducibly and compares the new model with the current champion on a fixed evaluation set. The new model moves forward only if it doesn’t lose on the metrics that matter.
Delivery then ships it in shadow mode (scoring live traffic without acting on it), then as a canary to a small share of users, with automatic rollback if metrics slip.
Continuous training
Google lists five retraining triggers: on demand, on a schedule, when new data arrives, when performance degrades and when inputs drift. Start with a schedule, and add drift-based triggers once monitoring is trustworthy. Automating retraining before you can detect a bad model only automates the damage.
Data and feature pipelines
Many production problems start in the data: a renamed column, a late upstream job, or a feature computed differently in training and serving (training–serving skew). Validation at both ends of the pipeline catches most of them.
A feature store such as Feast earns its place when several models share features or need them fresh at low latency. For one batch model, tested SQL in your warehouse is enough. If the warehouse itself is unreliable, fix that first: it is a data engineering problem.
How to tell when a model is going wrong
Models rarely crash when they go wrong; they return confident answers that slowly get worse. Monitoring needs four layers:
- Service health: latency, errors, throughput and cost per request.
- Data quality: missing values, out-of-range inputs, schema changes and volume drops.
- Drift: whether inputs (data drift) or the link between inputs and outcomes (concept drift) have shifted since training.
- Outcome quality: accuracy against real labels, and the business KPI the model exists to move.
Two caveats. Drift alerts are noisy and a shifted distribution doesn’t always mean worse predictions, so tune thresholds against real incidents. Labels also arrive late (a loan defaults months after approval), so lean on drift and proxy metrics until they do.
Every alert needs a named owner and a runbook covering when to roll back and when to retrain. Tools such as Evidently, Arize or the SageMaker and Vertex AI monitors compute the statistics; they don’t decide who gets paged.
What LLMs and agents add: evals, tracing, prompts and guardrails
If your product calls a hosted model such as GPT, Claude or Gemini, you may never train anything. You still need operations, because quality depends on prompts, retrieval, tool calls and a model version the provider can change or retire.
Evals replace accuracy scores
An eval is a repeatable test suite: realistic inputs, a definition of a good answer, and a grader. Anthropic’s guide to evaluating AI agents recommends code-based graders where possible, model-based graders where necessary, and human review to calibrate both. It suggests 20–50 simple tasks drawn from real failures as a good start, so a first suite is days of work.
Run evals in CI before any change to a prompt, model, retrieval index or tool. Then score sampled live traffic with the same graders, because production inputs are stranger than test sets.
Tracing and observability
One agent request can involve retrieval, several model calls and tool calls through Model Context Protocol (MCP) servers. Tracing records each step with inputs, outputs, tokens, latency and cost. The OpenTelemetry GenAI semantic conventions standardise this telemetry for model calls and MCP, and MLflow Tracing supports them natively, which keeps traces portable between vendors.
Prompt and model versioning
Treat prompts as code: version them, review changes, and record which prompt, model and index version produced each answer. Pin dated model snapshots rather than “latest” aliases where offered, and when a model is deprecated, run your evals against the replacement before switching.
Guardrails
The OWASP Top 10 for LLM applications is the standard checklist, led by prompt injection and sensitive information disclosure. Practical guardrails are input and output filters, PII redaction, least-privilege tool permissions, human approval for actions that move money or data, and spend limits. For adoption strategy, see our generative AI implementation guide.
Meeting governance, security and EU AI Act duties
Most governance falls out of good MLOps: the registry is your inventory, lineage your documentation and monitoring your log. The extra work is deciding who approves a release.
The EU AI Act applies if you place AI systems on the EU market or their output is used in the EU, wherever you are based. According to the European Commission, prohibitions have applied since 2 February 2025, general-purpose AI model obligations since 2 August 2025, and transparency rules from August 2026. After the AI Omnibus amendments, high-risk rules for areas such as employment, education and biometrics apply from 2 December 2027, and for AI in regulated products from 2 August 2028.
High-risk systems need risk management, quality training data, logging for traceability, documentation, human oversight, and accuracy, robustness and cybersecurity. Each maps to an MLOps practice. If you run hiring or credit-scoring models, record lineage now; retrofitting it later is far harder.
Outside the EU, the NIST Generative AI Profile offers a voluntary set of risks and actions, and ISO/IEC 42001 is a certifiable standard for AI management systems. Security basics still apply: access-controlled storage for model artefacts, and scanning of model files from public hubs.
Who you need and which tools to choose
You need a business owner for the KPI, a data scientist or AI engineer for the model and evals, an ML or platform engineer for pipelines and on-call, a data engineer, domain experts to label eval sets, and part-time compliance review. In a small company these are hats, not headcount.
Coding agents such as Claude Code, Codex and Cursor speed up pipeline code, but someone still owns the model when it misbehaves. If you lack platform skills, staff augmentation lets you borrow them while you decide whether to hire.
Add a tool layer only when its problem shows up. Managed platforms (SageMaker, Vertex AI, Azure Machine Learning, Databricks) trade fees and lock-in for less operations work; open-source stacks trade licence costs for engineering time.
| Layer | Open-source or self-hosted | Managed | Needed for the first model? |
|---|---|---|---|
| Experiment tracking and registry | MLflow | Weights & Biases, SageMaker, Vertex AI, Databricks | Yes |
| Pipeline orchestration | Airflow, Dagster, Prefect, Kubeflow Pipelines | Vertex AI Pipelines, SageMaker Pipelines | Yes, kept simple |
| Data validation and versioning | Great Expectations, DVC, lakeFS, dbt tests | Warehouse-native quality checks | Yes |
| Feature store | Feast | Databricks, Vertex AI, SageMaker | Only for shared or real-time features |
| Model serving | KServe, BentoML, Ray Serve; vLLM for open-weight LLMs | SageMaker and Vertex AI endpoints; Amazon Bedrock | Yes, unless batch-only |
| Monitoring and drift | Evidently | Arize, Fiddler, SageMaker Model Monitor | Yes |
| LLM tracing and evals | MLflow, Langfuse, Arize Phoenix | LangSmith, Braintrust, W&B Weave | Yes, for any LLM feature |
| Guardrails | NeMo Guardrails, Guardrails AI, Llama Guard | Amazon Bedrock Guardrails, Azure AI Content Safety | Yes, if user-facing |
A 90-day rollout plan, and how to measure the return
This plan takes one valuable model or LLM feature to level 1 maturity with a small team.
- Days 1–10, choose the target. Pick one model and one KPI. Record the baseline, the cost of a wrong output and who owns the outcome.
- Days 11–20, check data and risk. List data sources and personal data, and classify the use case under the EU AI Act.
- Days 21–35, make it reproducible. Version code, data references and configuration, set up tracking and a registry, and confirm anyone can rebuild the current model.
- Days 36–50, automate training and evaluation. Build the pipeline with data validation and an evaluation gate. For LLM features, wire an eval set built from real failures into CI.
- Days 51–65, deploy safely. Release via shadow or canary, with one-command rollback to the previous registry version.
- Days 66–80, monitor. Add health, data, drift and outcome dashboards, plus tracing for LLM features, with alerts that page a named owner.
- Days 81–90, review and decide. Compare with the baseline, write the runbook and model card, then add retraining, onboard a second model or stop.
Measuring the return
Separate the model’s value (its KPI change against a holdout group or baseline) from the value of operating it. MLOps shows up as speed (time from trained model to production, release frequency), reliability (incidents, time to detect and roll back), cost (infrastructure per 1,000 requests, engineer hours lost to manual retraining) and coverage (share of models with an owner, monitoring and passing evals).
Costs depend on the number of models, retraining frequency, real-time versus batch serving, GPU inference, regulatory class, and build versus buy. Be wary of fixed quotes from anyone who doesn’t know those six things. Our AI and ML deployment roadmap covers programme-level ROI.
How Pixelpk approaches this
Pixelpk Technologies is an AI and software development company founded in 2018, headquartered in Lahore with offices in Malaysia, the UK, Australia, Saudi Arabia and the US, and rated 4.9/5 on Clutch.
We build and run our own AI products in production: Pakistan LawBot for cited legal research and drafting in English and Urdu, Aivastark, one AI support and sales agent across website chat, WhatsApp, Instagram, Messenger, Telegram and email, and AITube, an AI-only video platform with a 20+ model studio.
Work with us as an Extended Team, a Managed Dedicated Team or through Custom Solution Development. See our AI solutions, or book a free strategy call.
Frequently asked questions
What is the difference between MLOps and DevOps?
DevOps automates building, testing and releasing code. MLOps applies the same ideas to systems whose behaviour also depends on data and trained models, adding dataset and model versioning, data validation, evaluation of each new model against the current one, drift monitoring and retraining. Most teams keep their DevOps tooling and add an ML layer on top.
How long does it take to implement MLOps?
For one important model, about 90 days is a realistic target for reproducible training, a registry, automated evaluation, safe deployment and monitoring. Expect longer if source data is unreliable, the use case is high-risk under the EU AI Act, or several teams must agree on a shared platform. Later models go faster because they reuse that work.
Do we need MLOps if we only use LLM APIs?
You need a lighter version. There are no training pipelines, but you still need evals that run before every prompt or model change, request tracing, versioned prompts, guardrails against prompt injection and data leakage, and cost monitoring. Providers update and retire models, and your evals tell you whether a replacement is safe to switch to.
What does MLOps cost a small or mid-sized company?
There is no honest single figure. Cost depends on how many models you run, how often they retrain, real-time versus batch serving, whether inference needs GPUs, the regulatory class of the use case, and managed versus open-source tools. Managed platforms cost more in fees and less in engineering time; open-source stacks reverse that trade.
Does the EU AI Act apply to our machine learning models?
It applies if you place AI systems on the EU market or their output is used in the EU, even if you are based elsewhere. Most business models, such as demand forecasting or recommendations, carry light obligations. Systems used for hiring, credit scoring, education or biometrics are high-risk, with stricter obligations applying from 2 December 2027.